−70% fewer tokens per answer
Curated, deduplicated context instead of raw document dumps — fewer tokens, fewer retries, lower bills on any model.
Observed in TensorLot pilot deployments, 2026.

TensorLot turns scattered enterprise documents into a trustworthy foundation for AI — so retrieval, assistants and agents work faster, more precisely and up to 70% cheaper. On any model.
Most enterprises sit on millions of documents: five versions of the same procedure, copies in forgotten sites, 2019 files that still rank first. Point an assistant or an agent at that and it answers with confidence — from the wrong file.
“Poor data quality is the #1 obstacle in GenAI projects.”
Gartner, 2025
Cleaning the data is not a side project. It is the foundation everything else stands on.
Clean data is not a nice-to-have. It is what makes every model, assistant and agent on top of it perform — measurably.
Curated, deduplicated context instead of raw document dumps — fewer tokens, fewer retries, lower bills on any model.
Observed in TensorLot pilot deployments, 2026.Answers point to the canonical version. Contradictions, duplicates and outdated copies are flagged before any model reads them.
People ask Tensor Bot, agents call one MCP endpoint — and get the right document, not five versions of it. Connect an agent in minutes, not sprints.
TensorLot Core reads your documents the way an auditor would — and shows you the verdict in one console.
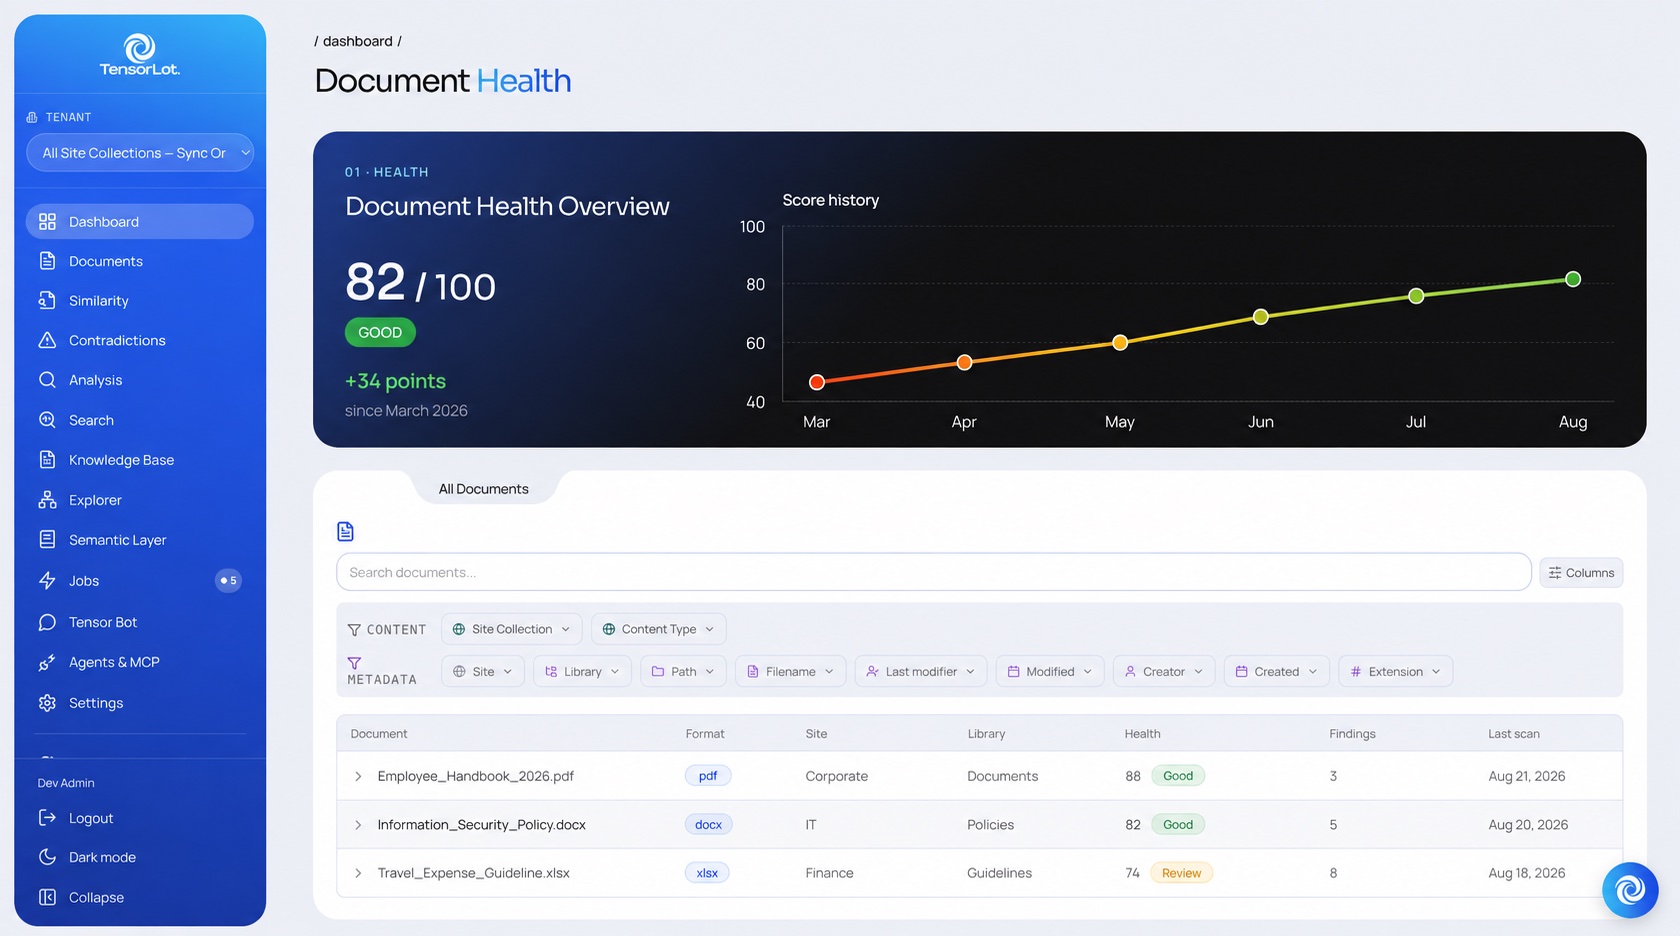
One health score for the whole tenant (82/100, +34 points since March) — and per document: format, site, library, health, open findings, last scan. Before any AI reads it.
TensorLot is the layer in between — not another silo. Your sources stay where they are; your models and agent frameworks stay your choice.
See your own SharePoint answered with citations — and what your agents would read — in a 30-minute demo.